

Comments, support and feedback
- 3 months ago
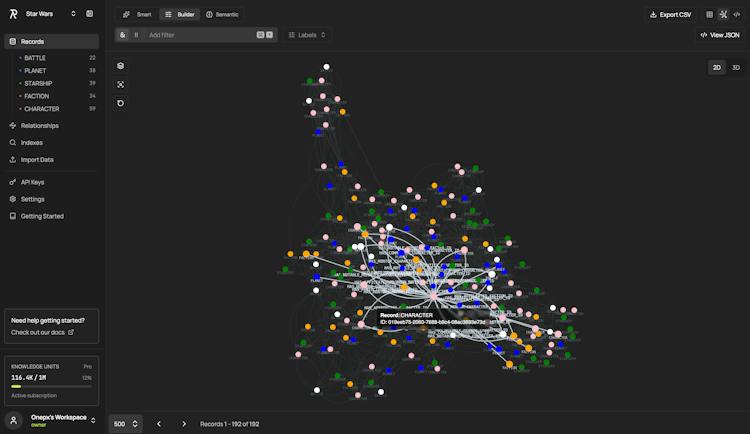
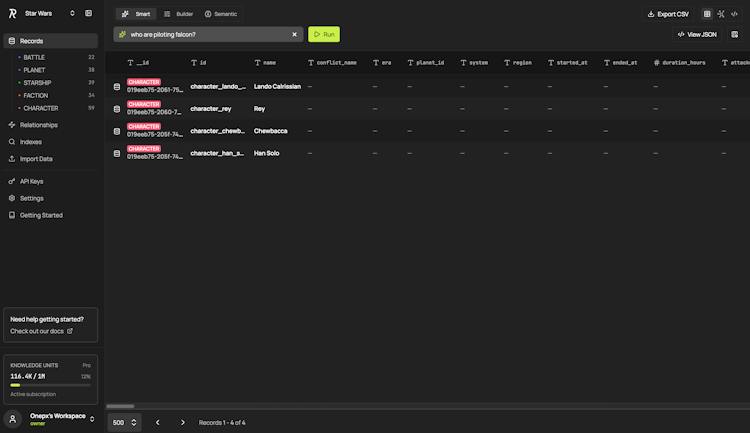
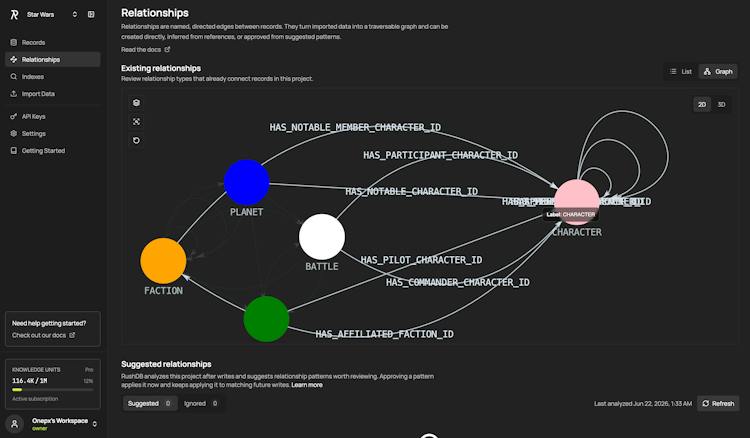
Pairing vector search with the graph layer is the interesting part for retrieval - agents can jump from a semantic match to connected context in one hop. Is the vector index built in, or do you bring your own embeddings?
- 3 months ago
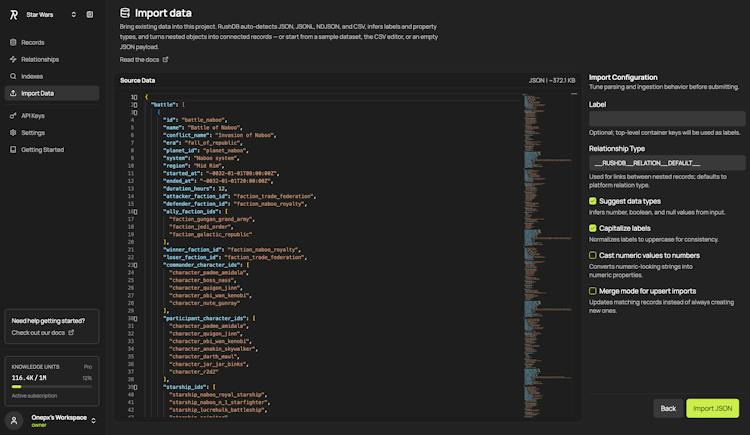
The no-schema "push any JSON, get relationship-aware records" is the part that sells it — schema migrations are exactly what kills using a real graph DB as agent memory. The thing I'd want to know before wiring it into an agent loop: across many writes of the same entity in slightly different shapes, does it dedup/merge into one node, or does each push create new ones? Unbounded node growth is what quietly turns agent memory into agent landfill. Built on Neo4j is reassuring either way — starring it.

About this launch
RushDB was launched by Artemiy Vereshchinskiy in June 23rd 2026.
- 3Upvotes
- 2205Impressions
- #8Week rank