AI pricing
AI model API pricing comparison
| Provider | Cached in | Context | ||||
|---|---|---|---|---|---|---|
| Nova Micro Bedrock on-demand standard tier, US pricing | Amazon (Bedrock) | $0.035 | $0.140 | — | — | $0.630 |
| Command R7B trial keys are free but rate limited and not for production | Cohere | $0.037 | $0.150 | — | 128K | $0.675 |
| Nova Lite Bedrock on-demand standard tier, US pricing | Amazon (Bedrock) | $0.060 | $0.240 | — | — | $1.08 |
| Ministral 3 3B batch 50% off | Mistral | $0.100 | $0.100 | $0.010 | — | $1.20 |
| GPT-OSS 20B Groq-hosted open model, ~1000 tokens/sec | Groqopen model | $0.075 | $0.300 | — | 131K | $1.35 |
| Ministral 3 8B batch 50% off | Mistral | $0.150 | $0.150 | $0.015 | — | $1.80 |
| Claude Haiku 5.5 prompts up to 100K tokens; over 100K: $0.50 in, $2.50 out, $0.05 cached. Batch 50% off | Anthropic | $0.100 | $0.500 | $0.010 | — | $2.00 |
| GPT-6 Luna long context (over 272K tokens): $0.20 in / $0.75 out; batch 50% off | OpenAI | $0.100 | $0.500 | $0.010 | — | $2.00 |
| Ministral 3 14B batch 50% off | Mistral | $0.200 | $0.200 | $0.020 | — | $2.40 |
| Qwen3.8 Flash | Together AIopen model | $0.150 | $0.470 | — | 1M | $2.44 |
| Mistral Small 4 batch 50% off | Mistral | $0.150 | $0.600 | $0.015 | — | $2.70 |
| GPT-OSS 120B Groq-hosted open model, ~500 tokens/sec | Groqopen model | $0.150 | $0.600 | — | 131K | $2.70 |
| GPT-OSS 120B | Together AIopen model | $0.150 | $0.600 | — | 131K | $2.70 |
| OpenAI GPT OSS 120B serverless standard mode; batch 50% off | Fireworks AIopen model | $0.150 | $0.600 | $0.015 | — | $2.70 |
| Codestral batch 50% off | Mistral | $0.300 | $0.900 | $0.030 | — | $4.80 |
| DeepSeek V4.1 Flash peak-hour rates (01:00–04:00 and 06:00–10:00 UTC on weekdays, cache miss); off-peak half price: $0.15 in / $0.60 out / $0.003 cached | DeepSeek | $0.300 | $1.20 | $0.006 | 1M | $5.40 |
| DeepSeek V4.1 Flash serverless standard mode; batch 50% off | Fireworks AIopen model | $0.300 | $1.20 | $0.006 | — | $5.40 |
| Gemini 3.1 Flash-Lite paid tier, text/image/video input; audio $0.50 in; batch 50% off | $0.250 | $1.50 | $0.025 | — | $5.50 | |
| Gemini 3.5 Flash-Lite paid tier; same price for text, image, video and audio input; batch 50% off | $0.300 | $2.50 | $0.030 | — | $8.00 | |
| Gemini 2.5 Flash deprecated: from Dec 1, 2026 requests route to Gemini 3.5 Flash-Lite. Text/image/video input; audio $1.00 in | $0.300 | $2.50 | $0.030 | — | $8.00 | |
| Nova 2 Lite Bedrock global cross-region standard tier; geo/in-region $0.33 in / $2.75 out | Amazon (Bedrock) | $0.300 | $2.50 | — | — | $8.00 |
| Mistral Large 4 batch 50% off | Mistral | $0.700 | $2.10 | $0.070 | — | $11.20 |
| Grok Build 0.1 prompts under 200K tokens; long-context rates apply to all tokens once prompt reaches 200K: $2 in / $4 out | xAI | $1.00 | $2.00 | $0.200 | 256K | $14.00 |
| Nova Pro Bedrock on-demand standard tier, US pricing | Amazon (Bedrock) | $0.800 | $3.20 | — | — | $14.40 |
| Gemini 3.8 Flash paid tier; introductory price through Dec 31, 2026, then $1.50 in / $7.50 out / $0.15 cached; batch 50% off | $0.750 | $3.75 | $0.075 | — | $15.00 | |
| Qwen3.8 27B preview model, may be discontinued at short notice | Groqopen model | $0.800 | $4.00 | — | 131K | $16.00 |
| Grok 4.3 prompts under 200K tokens; long-context rates apply to all tokens once prompt reaches 200K: $2.50 in / $5 out; no batch discount | xAI | $1.25 | $2.50 | $0.200 | 1M | $17.50 |
| Claude Haiku 4.5 batch 50% off; cached = cache hits (5m write 1.25x input) | Anthropic | $1.00 | $5.00 | $0.100 | — | $20.00 |
| GPT-6.1 Terra long context (over 272K tokens): $2 in / $7.50 out; batch 50% off | OpenAI | $1.00 | $5.00 | $0.050 | — | $20.00 |
| DeepSeek V4 Pro peak-hour rates (01:00–04:00 and 06:00–10:00 UTC on weekdays, cache miss); off-peak half price: $0.66 in / $1.98 out / $0.022 cached | DeepSeek | $1.32 | $3.96 | $0.044 | 1M | $21.12 |
| DeepSeek V4 Pro 0813 | Together AIopen model | $1.32 | $3.96 | $0.130 | 1M | $21.12 |
| GLM-5.3 | Together AIopen model | $1.40 | $4.40 | $0.260 | 1M | $22.80 |
| GLM 5.3 serverless standard mode; batch 50% off | Fireworks AIopen model | $1.40 | $4.40 | $0.260 | — | $22.80 |
| Grok 4.7 prompts under 200K tokens; long-context rates apply to all tokens once prompt reaches 200K: $4 in / $12 out; batch 20% off | xAI | $2.00 | $6.00 | $0.500 | 500K | $32.00 |
| Grok 4.6 prompts under 200K tokens; long-context rates apply to all tokens once prompt reaches 200K: $4 in / $12 out; batch 20% off | xAI | $2.00 | $6.00 | $0.500 | 500K | $32.00 |
| Qwen 3.8 Max serverless standard mode; batch 50% off | Fireworks AIopen model | $2.00 | $6.00 | $0.250 | — | $32.00 |
| Gemini 2.5 Pro deprecated: from Dec 1, 2026 requests route to Gemini 3.8 Flash. Prompts up to 200K tokens; over 200K: $2.50 in / $15 out | $1.25 | $10.00 | $0.125 | — | $32.50 | |
| Nova 2 Pro (Preview) preview; Bedrock global cross-region standard tier | Amazon (Bedrock) | $1.25 | $10.00 | — | — | $32.50 |
| Claude Sonnet 5.5 batch 50% off; cached = cache hits (5m write 1.25x input) | Anthropic | $2.00 | $10.00 | $0.100 | 1M | $40.00 |
| Claude Sonnet 5 batch 50% off; cached = cache hits (5m write 1.25x input) | Anthropic | $2.00 | $10.00 | $0.200 | 1M | $40.00 |
| GPT-6.1 Sol long context (over 272K tokens): $4 in / $15 out; batch 50% off | OpenAI | $2.00 | $10.00 | $0.100 | — | $40.00 |
| Gemini 4 Argon paid tier; introductory price through Nov 30, 2026, then $4 in / $20 out / $0.20 cached; batch 50% off | $2.00 | $10.00 | $0.100 | — | $40.00 | |
| Gemini 3.1 Pro Preview preview; prompts up to 200K tokens. Over 200K: $4 in / $18 out; batch 50% off | $2.00 | $12.00 | $0.200 | — | $44.00 | |
| Command A trial keys are free but rate limited and not for production | Cohere | $2.50 | $10.00 | — | 256K | $45.00 |
| GPT-5.3 Codex Codex model; fast mode costs 2x | OpenAI | $1.75 | $14.00 | $0.175 | — | $45.50 |
| Claude Sonnet 4.6 batch 50% off; cached = cache hits (5m write 1.25x input) | Anthropic | $3.00 | $15.00 | $0.300 | 1M | $60.00 |
| Kimi K3 serverless standard mode; batch 50% off | Fireworks AIopen model | $3.00 | $15.00 | $0.300 | — | $60.00 |
| Claude Opus 5.5 batch 50% off; cached = cache hits (5m write 1.25x input) | Anthropic | $4.00 | $20.00 | $0.200 | 1M | $80.00 |
| Claude Opus 5 batch 50% off; cached = cache hits (5m write 1.25x input) | Anthropic | $5.00 | $25.00 | $0.500 | 1M | $100 |
| Claude Fable 5.1 batch 50% off; cached = cache hits (5m write 1.25x input) | Anthropic | $10.00 | $50.00 | $0.250 | 1M | $200 |
| GPT-6 Astra long context (over 272K tokens): $20 in / $75 out; batch 50% off | OpenAI | $10.00 | $50.00 | $1.00 | — | $200 |
Last checked earlier: Cohere (2026-10-08), Amazon (Bedrock) (2026-10-08).
Need benchmarks and specs too? LLM Models compares models in depth. Building with them? See AI dev tools and open-source ChatGPT alternatives. To price a real prompt, paste it into the token counter.
FAQ
Which AI model API is cheapest?+
By list price per 1M tokens, Nova Micro (Amazon (Bedrock)) is the cheapest on this page: $0.035 input and $0.14 output. Cheaper is not always better: compare quality on your own prompts, and use cached input and batch discounts where providers offer them.
How are these prices measured?+
US dollars per 1 million tokens, standard (non-batch) tier, from each provider's official pricing page on 2026-11-02. Where a price depends on prompt length or time of day, the base tier is shown and the note explains the rest.
What does the "Your month" column mean?+
It multiplies each model’s input and output prices by the monthly token volumes you type above the table, so you can compare what the same workload costs on every model.
Embed this table
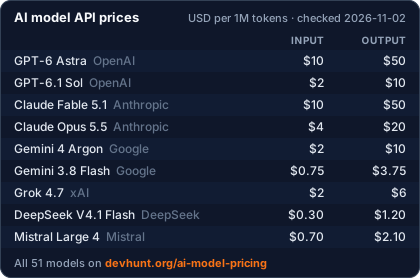
Flagship model prices as an image for your README, docs or blog. It updates when we re-check prices.
[](https://devhunt.org/ai-model-pricing)