Kurate.org
AI-powered scientific paper rankings
Free2,696 impressions#18 of its week1 comment
Comments
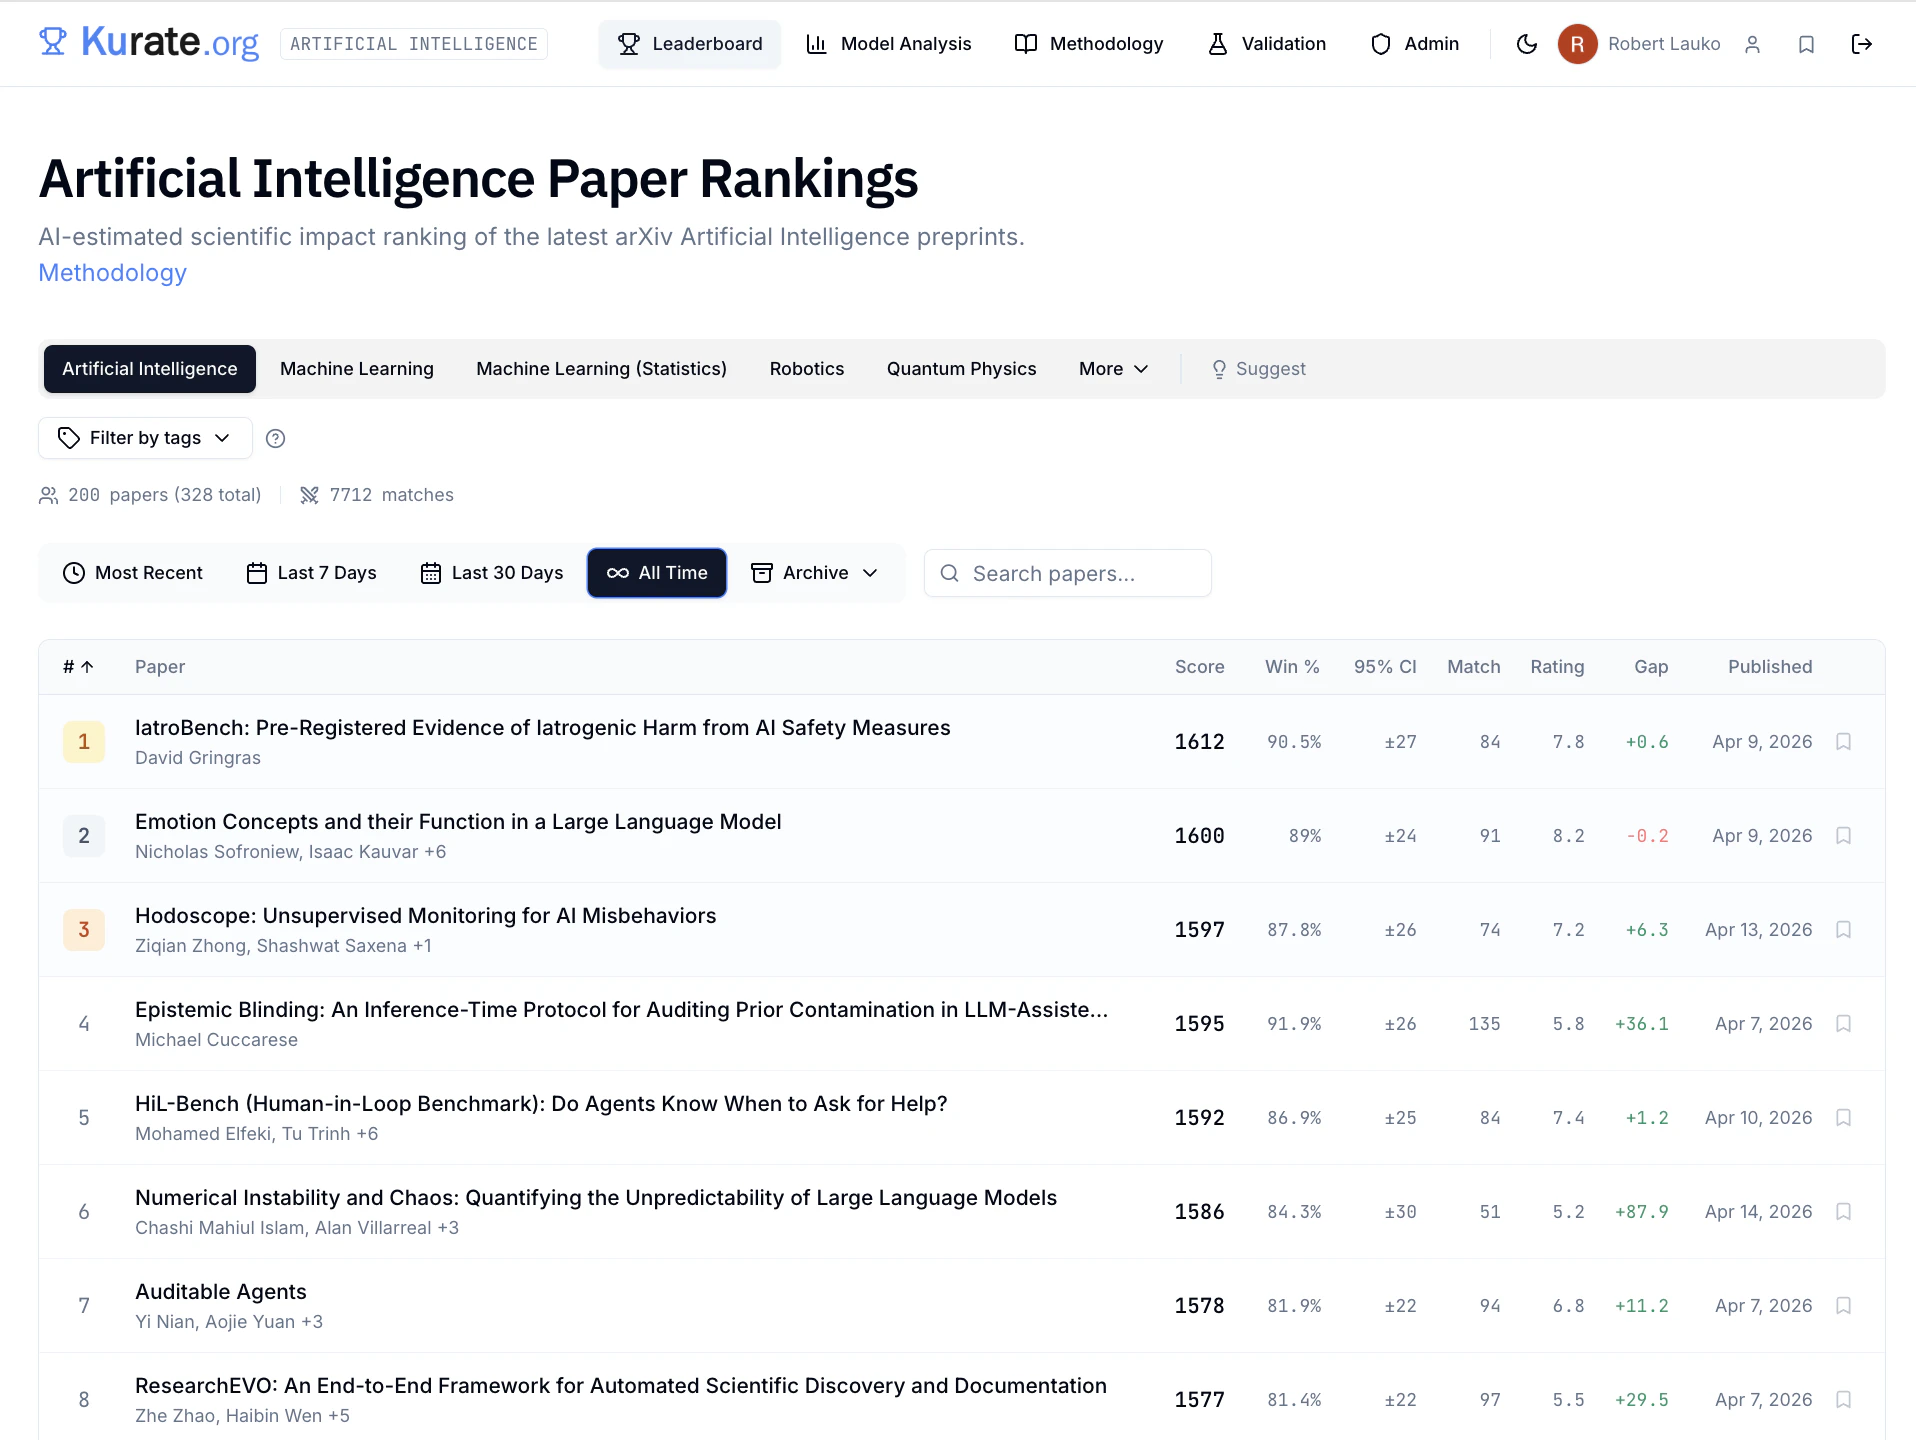
>log in to commentScientific publishing is broken. Peer review takes months, reviewers are underpaid and overloaded, and the publish-or-perish culture along with AI-assisted writing leads to a flood of daily preprints (almost 1,000 preprints on arXiv.org alone). The result: important papers get buried, mediocre ones get accepted at top venues, and researchers spend more time gaming the system than doing science. Kurate is inspired by LMArena's approach to ranking LLMs through head-to-head comparisons. How it works: Every new arXiv preprint from multiple scientific disciplines gets an AI-generated impact assessment, then papers are paired up and three LLM judges (GPT-5.4, Claude Opus 4.6, Gemini 3 Pro) vote on which has higher scientific impact. Thousands of these pairwise matches produce ranked leaderboards with Elo-style scores. See https://kurate.org/methodology for more details. Claude Opus 4.6 dominates as both summarizer and judge. It's the only model that uses the full 1–10 score range (GPT and Gemini cluster everything at 7–8) and creates very few inconsistencies through intransitive loops (from A>B and B>C it should follow A>C). See https://kurate.org/correlation for more. First validation tests on ICLR datasets have shown promising correlation (ρ = 0.6–0.7) with human reviewers and program committees. See the ongoing validation at https://kurate.org/validation?v=... Kurate and the validation in particular are still a work in progress. Would love feedback, especially from researchers. Does this match your intuition about paper quality?

AI-powered rankings of arXiv preprints across 16 impact dimensions.
- for
- Researchers, students, labs, institutions and science analysts.
Key features
- 16-dimensional scoring — Each paper is rated on 16 metrics such as significance, rigor, novelty and reproducibility.
- Frontier AI assessment — Claude Opus 5 reads full-text papers and generates scores with written justifications.
- Interactive heatmap explorer — Color-coded grid lets users sort, filter and set thresholds across categories and dates.
- Impact rating — A single 1-to-10 impact score summarises each paper’s overall potential.
- Live statistics & correlations — Automatic updates show distribution trends and metric correlations across the dataset.
- Weekly personalized digest — Email delivers top papers matching user-defined filters every Monday.
Use cases
- Identify high-impact preprints in a specific arXiv category.
- Set metric thresholds to find novel and rigorous papers for literature reviews.
- Monitor emerging research trends for a research group or institution.
- Curate weekly reading lists for students or lab meetings.
Kurate.org FAQ
What does Kurate rank?+
Kurate ranks scientific preprints from arXiv, scoring each on 16 AI-generated metrics.
How are papers ranked?+
Claude Opus 5 reads the full paper, assigns a 1-10 score for each metric, and aggregates them into an overall impact rating.
Are Kurate rankings the same as peer review?+
No, they are discovery signals meant to highlight papers worth reading, not a substitute for formal peer review.
Can I browse rankings by category?+
Yes, rankings are organized by arXiv categories and can be filtered in the heatmap view.
How often are rankings updated?+
The platform continuously ingests new arXiv papers and updates scores in real time.
Summarized by DevHunt from kurate.org · Oct 1, 2026. Details may change; check the official site.


