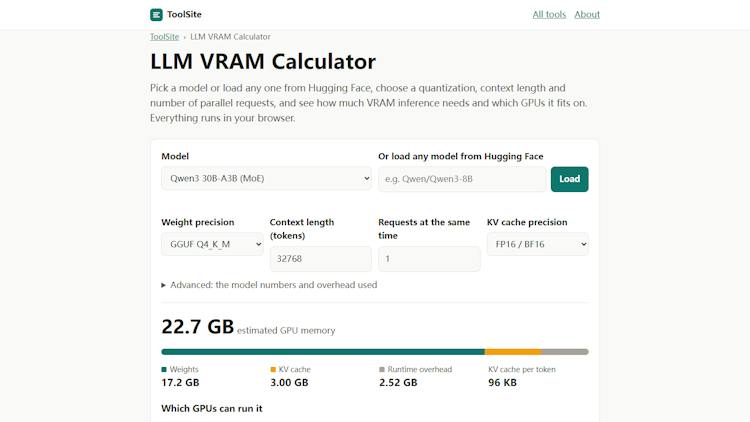
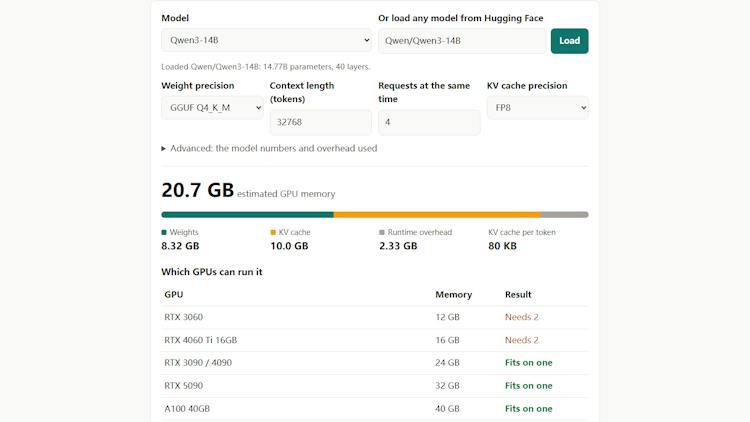
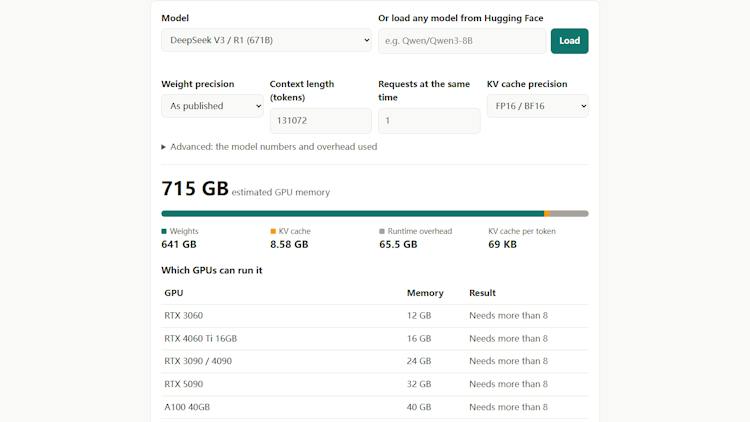
Paste a Hugging Face model id (or pick a preset), choose a quantization and context length, and it shows how much GPU memory inference needs: weights, KV cache and overhead, plus which GPUs it fits on.
It reads config.json and the safetensors metadata straight from the Hub, so new models work the day they are uploaded. MoE, DeepSeek's MLA cache, sliding-window layers and MXFP4 are handled; for gpt-oss and DeepSeek V3 the weight numbers match the real checkpoint sizes.
Free, no sign-up, runs in your browser. The calculation code is MIT on GitHub.
Classified in
Comments, support and feedback
About this launch
LLM VRAM Calculator by Zelong Fang Will be launched July 31st 2029.